
Reasoning models aren't everything
No, simply plugging in the latest, super-powerful model from OpenAI, Anthropic, or Google isn't enough to create an AI agent that's effective, high-performing, and embraced by your team or your customers.




You’ve invested in RAG models and pipelines. Your results are still not good enough to move to production with confidence. Our audit tells you exactly where your knowledge is lacking, which sources to address first, and how to scale up without another stalled POC.


When it comes to generative AI projects in businesses, the same pattern keeps repeating itself.
Two truths we hear from all our clients before they call us.


No, simply plugging in the latest, super-powerful model from OpenAI, Anthropic, or Google isn't enough to create an AI agent that's effective, high-performing, and embraced by your team or your customers.
Your document repository needs to evolve to be “AI-ready.” Formatting, rewriting, automation—there are several projects that need to be addressed urgently.
With AI, false or outdated content is no longer just an isolated mistake: it spreads instantly, with every interaction, across every channel, and to every advisor.
Does this sound familiar? That's exactly what we see before every procedure.
Talk to an expert
To get the most out of AI and LLMs, go back to the basics: understanding and engaging with your end users.
An unanswered question during the purchasing process leads to a cart abandonment.
A 20% increase in conversion rates on key customer journeys when the answer is included in the purchase journey
Every minute spent searching is one minute less spent advising.
-50% reduction in search time (ranging from -10% to -30%, depending on the complexity of the requests)
An incorrect or missing answer creates a new lead, then another, and yet another...
A 30% to 35% decrease in customer service requests thanks to self-service (ranging from 30% to 75%)
CIOs and Customer Relations/Operations departments are not looking for the same things in an AI audit. Our method provides a common foundation and two perspectives that resonate with each group.
Assess the technical feasibility of your RAG projects or AI assistants before making any budgetary commitments
Avoid POCs that never make it into production due to poor documentation quality
A common language with the business: a score for each source—quantified and justifiable
Plan for the data preparation workload well in advance of the go-live dates
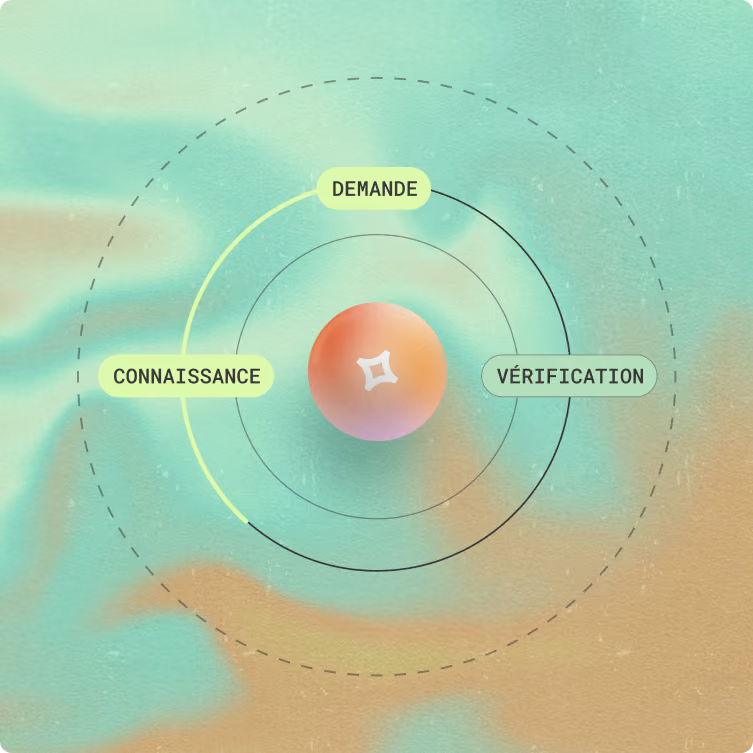
An AI assistant that actually responds—to real issues.
Prioritize optimizations for the topics that generate the most questions in management
Reduce the time your advisors spend searching for the right information across multiple sources
An actionable roadmap for your knowledge teams, with measurable business impacts
An evaluation framework that ensures the reliability of responses before going live

Our belief is that we must approach the project from the perspective of actual use, prioritizing the areas that raise the most questions—and thus have a direct impact on your teams’ work and your customers’ satisfaction.
Talk to a Smart Tribune ExpertA comprehensive overview of the knowledge and documentation available for your AI projects. Workshops, algorithmic scoring, and expert analysis.
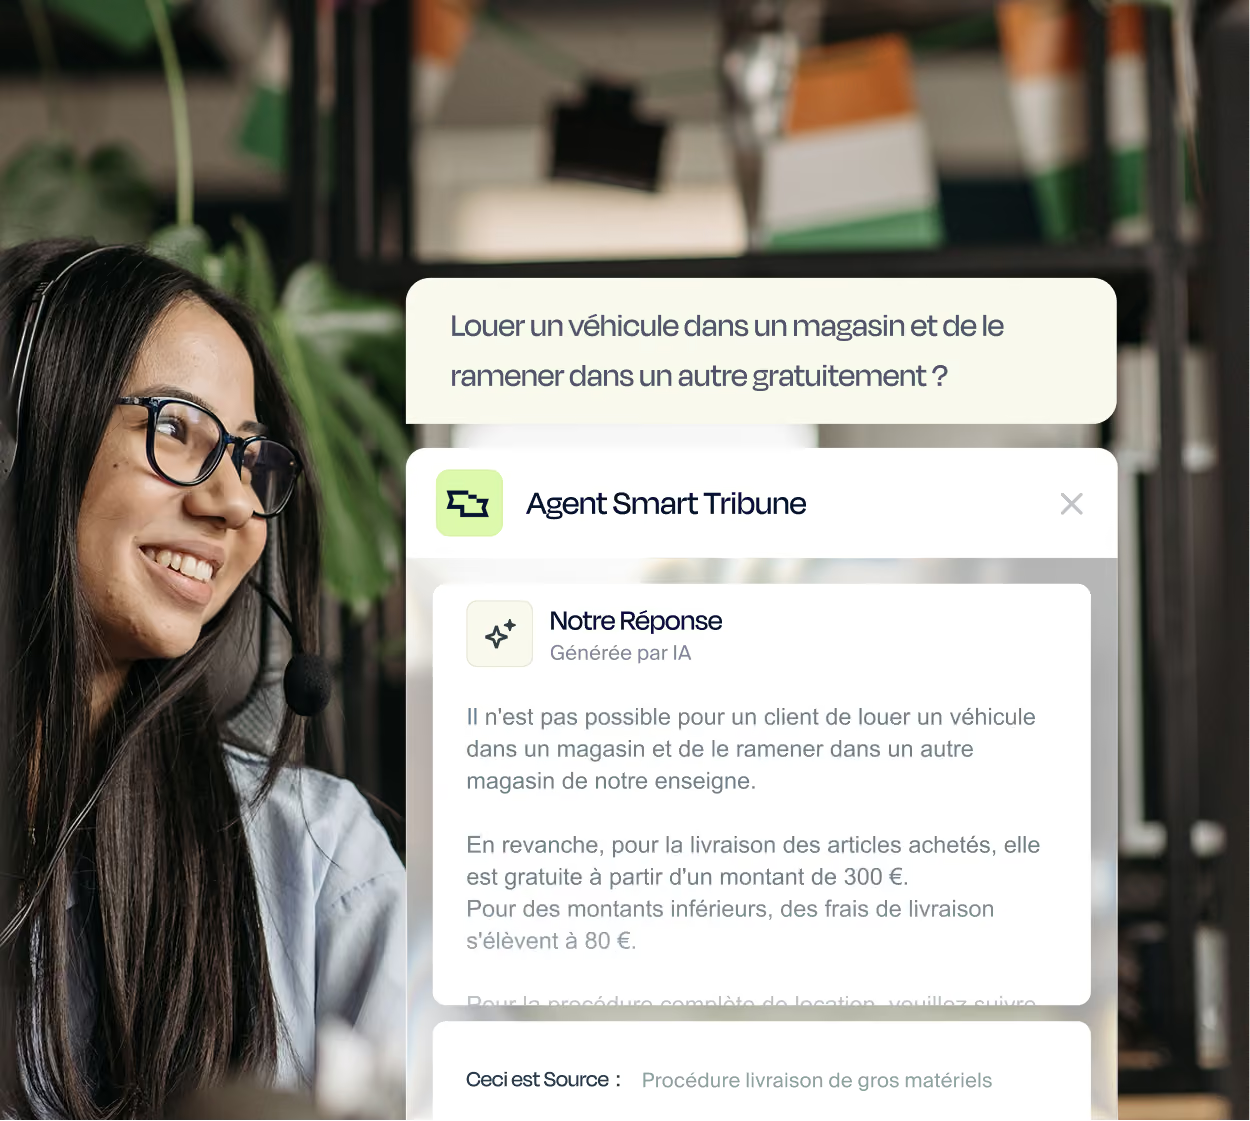
A clear understanding of “who” and “why”: identifying the major pain points experienced by your teams in the field, prioritizing topics with a high volume of questions, the level of detail expected in responses, and risk tolerance.
Teams committed to long-term transformation—and, above all, a governance structure that prevents your infrastructure from becoming obsolete again. An audit is only worthwhile if the knowledge remains up to date after we leave.
Simply bringing all the teams together around the mapping exercise revealed previously untapped sources of knowledge.
By scoring all these sources, we can provide you with a roadmap for automation and optimization to get your team on board with this essential project.

Identified knowledge silos
: “Example of an audit conducted in July 2026”
Documents and articles analyzed
, “Example of an audit conducted in July 2026”
Average score from primary sources
"Example of an audit conducted in July 2026"

Our AI relies exclusively on your content and cites its sources in every response: reliable and traceable information.

Approval workflows, content freshness, team-based permissions, traceability. Compliant with the AI Act.

Multiple template providers and automatic switching, so there is no reliance on a single template.
ANALYSIS OF YOUR BUSINESS KNOWLEDGE...
Receive an encrypted document detailing your volumes, with the assumptions clearly stated, that you can present internally without us.
Get my free audit